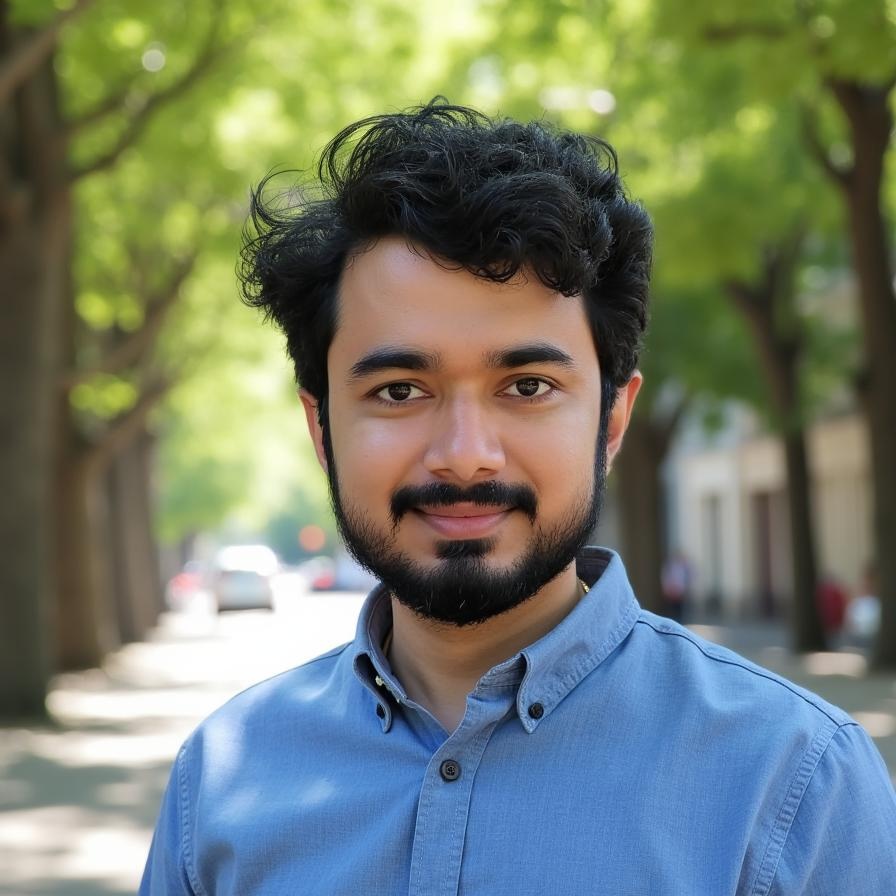
I’m an ML generalist with a specialization in audio and speech, currently an Applied Scientist on the AGI Foundations team at Amazon. I’m a core contributor to the Nova 2 family of multimodal LLMs, where I focus on multimodal post-training and evaluation for real-time production use.
My work is centered on making AI usable in the real world: dependable in production, aligned with user expectations, and responsive in real-time. I’ve led spoken interaction quality work, shipped product-aligned model improvements, and built evaluation, benchmarking, and release-gating pipelines that enable faster iteration without regressions.
Previously, I was a Founding Engineer at Telling.ai, where I led development of speech-first AI systems for longitudinal respiratory health monitoring using voice and breath sounds, and helped take research prototypes into clinical-grade production systems.
I have over 8 years of experience in AI research and engineering. I hold a research master’s degree in Language Technologies from Carnegie Mellon University and a bachelor’s degree from IIT Guwahati.
Outside of work, I enjoy obsessively optimizing my coffee—and then applying the same mindset to rapidly prototyping ideas. A recent project, LLM Powered After Visit Summary, was selected for a panel discussion at the American Academy of Ophthalmology.
I’m best reached at rk.kuls [at] gmail.com. More details are in my CV. A full list of my publications can be found here and on Google Scholar.